5 Hypothesis testing
A large number of scientific questions can be expressed as an hypothesis test—essentially a yes/no question, such as “are two samples drawn from distributions with the same mean?”, or “Is the frequency of an allele in a population greater than 0.1?”. Several tests have been developed, each with a specific type of question in mind. There is a dangerous tendency to view statistics as a collection of tests, and to practice it by plugging in your data set into the correct test, expecting that the test will spit out the correct decision. The purpose of this lesson is to demonstrate that using and interpreting statistical tests requires careful thinking to avoid serious errors.
5.1 Test results vs. the truth
A statistical test begins by stating the null hypothesis, usually one that is expected, or that shows no effect: for example, that two samples come from a distribution with the same mean, or that a rare allele has frequency of less than 0.1. One may state the alternative hypothesis explicitly, although it’s usually the logical converse of the null, i.e., the two samples have different population means, or the allele has frequency greater than 0.1.
After the hypothesis is stated, the data are collected and are used to test the hypothesis. By default, the null hypothesis is assumed to be true, and the test assesses whether the data provide sufficient evidence against the null hypothesis—in which case the null hypothesis is rejected. There is an adversarial relationship: either the data knock off the hypothesis, or else they fail to do so. Standard terminology reflects this somewhat counter-intuitive setup: rejecting the null hypothesis is called a positive test result, while not rejecting it is called a negative result.
The fundamental assumption of this process is that the truth value of the hypothesis is set prior to the collection of data. For example, if one could observe all of the genomes, the frequency of the allele would be known exactly, so this truth exists prior to the hypothesis testing. Because we typically can only observe a sample (and not the entire universe of data), we might end up erroneously rejecting the null hypothesis when it is in fact true, or not rejecting it when it is in fact false. The possible outcomes of a test can be organized in the table:
| H0 | True | False |
|---|---|---|
| Reject | False Positive | True Positive |
| Not Reject | True Negative | False Negative |
The values at the top describe the truth status of the hypothesis, while the decisions in the left column are the result of using data to test the hypothesis. Note: the words false and true in describing the test result do not refer to the hypothesis, but to whether the result is correct! For example, if the frequency of the allele were 0.09 but the test for the hypothesis that the frequency is less than 0.1 resulted in rejecting that hypothesis, that would be a false positive result (the null hypothesis is true but the test rejected it.)
5.2 Types of errors
As mentioned above, sometimes a hypothesis test makes the wrong decision, which is called an error. There are two different kinds of errors: rejecting a true null hypothesis, called a Type I error, and not rejecting a false null hypothesis, called a Type II error.
Example: In the case above of testing for the same mean: if the samples are taken from distributions with the same mean, but the hypothesis is rejected, this is called a false positive (Type I error). If the samples come from distributions with different means, but the hypothesis is not rejected, this is called a false negative (Type II error.)
As a scientist, would you rather make a Type I error (make an erroneous discovery), or a Type II error (fail to make a discovery)?
5.3 Test parameters and p-values
The sensitivity of a test is the probability of obtaining the positive result, given a false hypothesis; and the specificity of a test is the probability of obtaining the negative result, given a true hypothesis. The Type I error rate is the probability of obtaining the positive result, given a true hypothesis (complementary to specificity), and the Type II error rate is the probability of obtaining the negative result, given a false hypothesis (complementary to sensitivity).
All four parameters (rates) of a binary test are summarized as follows: \[\text{Sen} = \frac{TP}{TP+FN}; \; \text{Spec} = \frac{TN}{TN+FP}\] \[\text{FPR} = \frac{FP}{TN+FP}; \; \text{FNR} = \frac{FN}{TP+FN}\] The notation TP, FP, etc. represents the frequency or count of true positives, false positives, etc., out of a large number of experiments with known truth status of the hypothesis.
Knowledge of sensitivity and specificity determine the Type I and Type II error rates of a test since they are complementary events.
Of course, it is desirable for a test to be both very sensitive (reject false null hypotheses, detect disease, convict guilty defendants) and very specific (not reject true null hypotheses, correctly identify healthy patients, acquit innocent defendants), but no test is perfect, and sometimes it makes the wrong decision. This is where statistical inference comes into play: given some information about these parameters, a statistician can calculate the error rate in making different decisions.
The probability that a given data set is produced from the model of the null hypothesis is called the p-value of a test. More precisely:
For a given data set \(D\) and a null hypothesis \(H_0\), the p-value is the probability of obtaining a result as far from expectation or farther than the observed data, given the null hypothesis.
The p-value is the most used, misused, and even abused quantity in statistics, so please think carefully about its definition. One reason this notion is frequently misused is because it is very tempting to conclude that the p-value is the probability of the null hypothesis being true, based on the data. That is not the case! The definition has the opposite direction of conditionality—we assume that the null hypothesis is true, and based on that calculate the probability of obtaining a pattern as extreme or more extreme than what observed in the data. There is no way (according to classical “frequentist” statistics) of assigning a probability to the truth of a hypothesis, because it is not the result of an experiment.
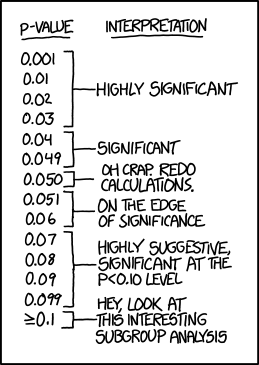
Typically, one sets a critical threshold bounding the probability of making a Type I error in a test to a “small” number (often, \(\alpha = 0.05\) or \(0.01\)), and calls the result of a test “significant” if the p-value is less than \(\alpha\).
For example, consider samples of size \(n\) taken from two normal distributions (with unobserved means \(\mu_1\), \(\mu_2\)). We can generate the data:
and use a Student’s t-test to probe whether the means differ:
Exercise: Can you detect a “significant difference in means” (assuming \(\alpha = 0.05\))? What if you take a much larger sample? What if the difference in means is more pronounced?
5.4 Multiple comparisons
What if we were to produce several samples? E.g., measure difference between males and females reflectance in birds at several locations? Suppose that in fact the reflectance is the same for male and female (\(\mu_1 = \mu_2 = 1\)), that for each location we capture and measure 10 males and 10 females, and that we repeat this across 2500 locations.
First, let’s write a little function that returns the p-values for the t-test
and now simulate the data:
How many times do we detect a “significant difference in reflectance” when setting \(\alpha = 0.05\) (even though we know that males and females are sampled from the same distribution)?
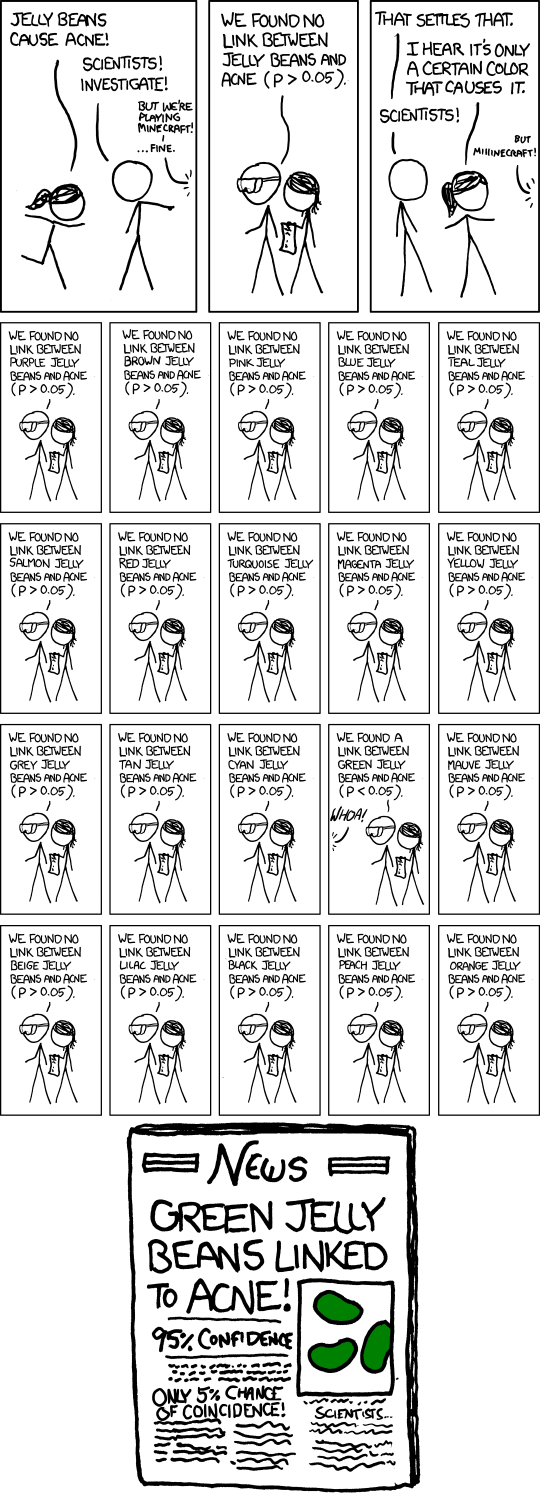
You should get a number of “significant” tests that is about \(2500 \cdot 0.05 = 125\). In fact, the distribution of p-values when the data are sampled from the null hypothesis is approximately uniform:
This means that when you are performing multiple tests, some will turn out to find “significant” differences even when there are none. Again, this is better summarized by xkcd:
Exercise: what happens to the distribution of p-values if the means are quite different (e.g., \(\mu_1 = 1\), \(\mu_2 = 0.9\))?
5.5 Corrections for multiple comparisons
The main approach to deal with the problem of multiple comparisons is to adjust the p-values. For example, in Bonferroni correction one consider as significant test results whose associated p-value is \(\leq \alpha / n\), where \(n\) is the number of tests performed (equivalently, redefine the p-values as \(p' = \min(p n, 1)\). Clearly, this correction becomes overly conservative when the number of tests is large. For example, in biology:
Gene expression In a typical microarray experiment, we contrast the differential expression of tens of thousands of genes in treatment and control tissues.
GWAS In Genomewide Association Studies we want to find SNPs associated with a given phenotype. It is common to test tens of thousands or even millions of SNPs for significant associations.
Identifying binding sites Identifying candidate binding sites for a transcriptional regulator requires scanning the whole genome, yielding tens of millions of tests.
The funniest example of this problem is the fMRI of the dead salmon: a dead salmon “was shown a series of photographs depicting human individuals in social situations with a specified emotional valence. The salmon was asked to determine what emotion the individual in the photo must have been experiencing.” The researchers showed that if multiple comparisons were not accounted for, one would detect a cluster of active voxels in the brain, with a cluster-level significance of p = 0.001.
The widespread use of GWAS and other techniques that are trying to find a needle in a haystack led to the development of many interesting techniques. Here an interesting account.
Adjusting p-values in R:
5.6 Two problems with science
5.6.1 Selective reporting
We have seen above that setting \(\alpha = 0.05\) means that we are going to make false discoveries at this rate. In science, we prefer publishing positive results—negative results are difficult to publish and attract little attention. Suppose that 20 research groups around the world set out to test the same hypothesis, which is false. Then there is a good chance at least one group will reject the null hypothesis, and pursue publication for their “discovery”. The tendency to put negative studies in the files drawer and forget about them causes the so called publication bias (aka selective reporting): by favoring positive results over negative ones, we greatly increase the chance that our conclusions are wrong. Note that these would cause the results of the paper to be largely impossible to reproduce, and the reproducibility crisis in the sciences is partially due to selective reporting.
5.6.2 P-hacking
One big violation of good experimental design is known as p-value “fishing” (or p-hacking): repeating the experiment, or increasing the sample size, until the p-value is below the desired threshold, and then stopping the experiment. Using such defective design dramatically lowers the likelihood that the result is a true positive. And of course there is actual fraud, or fudging of data, which contributes to some bogus results.
An insidious cousin of p-hacking was dubbed by Andrew Gelman “the garden of forking paths” in this paper. The issue arises in complex problems with multi-variable noisy datasets (aren’t all interesting ones like that?) Essentially, with many choices and degrees of freedom in a problem, it is easy to convince yourself that the choice you made (data cleaning, parameter combinations, etc.) is the correct one because it gives the strongest results. Without a clearly stated hypothesis, experimental design, and data processing details prior to data collection, this enchanted garden can lead even a well-intentioned researcher astray.
5.7 Readings
Good readings on these and related issues:
5.8 How to fool yourself with p-hacking (and possibly get fired!)
We are going to try our hand at p-hacking, to show how easy it is to get fooled when you have a sufficiently large and complex data set. The file data/medals.csv contains the total number of medals won at the Olympic games (Summer or Winter) by country, sport and gender. We have a simple, and reasonable (?) hypothesis: because the amount of money available to Olympic teams is finite, whenever a country invests in the male team, this will be at the detriment of the female team. To test this hypothesis, we measure whether the number of medals won by a national female team in a year is negatively correlated with the number of medals won by the male team.
Let’s read the data, and take a peak:
First, let’s see whether our hypothesis works for the whole data:
The correlation is positive: more medals for the men tend to correspond to more medals for the women. This correlation is not very strong, but is it “significant”? We can run a correlation test:
Indeed! The confidence intervals are far from 0: the correlation is definitely positive. Should we give up? Of course not! Just as for the jelly beans, we can p-hack our way to glory by subsetting the data. We are going to test each discipline independently, and see whether we can get a robustly negative correlation for any discipline. Because we are serious scientists, we are going to consider only disciplines for which we have at least 50 data points, to avoid results that are due to small sample sizes. Let’s write a code:
Now let’s see whether there are highly significant negative correlations:
Let’s plot our results to convince ourselves that they are strong:
That’s it! Should we rush to publish our results? Not quite: we have p-hacked our way to some highly significant results, but we did not correct for the number of tests we’ve made, and what we would do is to selectively reporting our strong results. In fact, we can do something very simple to convince ourselves that our results do not make much sense: just run the code again, but reporting significant positive correlations…
You can see that we’ve got about the same number of sports testing significant for positive correlation! Bonus question what about figure skating?
5.9 Multiple hypothesis testing and p-value corrections
Many times in science, one has to perform hypothesis tests on separate, independent questions; e.g. test 20 patients for a disease. This can lead to higher probability of errors in the aggregate: if we test 20 healthy patients using a test with a false positive rate of 0.05 (like using a significance level of 0.05), then the probability of at least one of the tests being a false positive is much higher than 0.05, as can be calculated from the binomial distribution:
\[P(k>0; p=0.05, n=20) = 1 - P(k=0; p=0.05, n=20) = 1-0.95^{20} \approx 0.64\]
This is a particular problem in several situations, for example when multiple groups perform similar studies, but only the ones that return a positive result are published (see our discussion about publication bias in the last chapter). It is also a problem when there are multiple associations between different variables tested in the same study. If one applies a significance level of 0.05 or 0.01, one may end reporting a lot of false positive results (depending on the number of different hypotheses tested). What can be done about it?
5.9.1 Bonferroni correction
The simplest approach is called the Bonferroni correction. The method is straightforward: if you perform \(n\) independent test and want to control the probability of making at least one false positive error, then you need to reduce the significance level by the factor of \(n\); \(\alpha_B = \alpha /n\). The result of this adjustment is to make sure the probability of making at least one error out of \(n\) tests (what is known as the “Family-wise error rate”) is equal to the significance level \(\alpha\). If you want to be pedantic, it’s only approximately true: for example, in the case of the scenario described above, the probability of at least one error with the Bonferroni correction will be
\[P(k>0)=1−P(k=0;p=0.05/20,n=20)=1−(1-0.05/20)^{20} ≈ 0.0488\]
The Bonferroni correction is a blunt instrument: it dramatically reduced the number of false positives, but it also makes real effect difficult to detect. For that reason it is considered a conservative method for multiple hypothesis testing, and more sophisticated methods are often preferred.
5.9.2 FDR correction
A more effective approach aims to control the False Discovery Rate (FDR) instead of the Family-wise error rate. The FDR is defined as the complement of the PPV, that is the fraction of false positives out of all positive results. Essentially, instead of trying to avoid even a single false positive, let’s control the fraction of false positive results.
One of the best methods is called the Benjamini-Hochberg method, which is far more complicated than Bonferroni. The procedure follows the following steps, given n p-values and a chosen FDR level q (e.g. 0.05):
Sort the p-values in ascending order: \(p_1 ≤ p_2 ≤ … ≤ p_n\) keeping track of which hypothesis each belongs to.
For each rank i, compute the BH critical value (i/n)·q.
Find the largest rank k for which \(p_k ≤ (k/n)·q\).
Reject (declare significant) all hypotheses with rank 1 through k — even any whose own p-value exceeded its individual critical value.
5.10 GWAS simulator
The following simulates the results of a Genome-wide association study, which tests multiple alleles (SNPs) for association with a trait (e.g. height), and this trait is numeric and is normally distributed. This simulator assumes that a certain number of SNPs (which you can control with a slider) are associated with the trait, that is the height of the people with this SNP are different than for those without it. The mean difference in the height distributions for a SNP with an effect is set by another slider, measured in terms of standard deviations of the trait. You can also control the sample size, that is the number of people in the study.
The result of a GWAS is a number of independent hypothesis tests (one for each SNP) which all return a p-value. Then a researcher has to decide on the appropriate significance threshold (e.g. 0.01 or 0.05), below which the hypothesis is rejected. The simulator allows you to choose between three significance levels, as well as to apply one of two kinds of p-value adjustment: the Bonferroni correction or the FDR (Benjamini-Hochberg) correction.
#| '!! shinylive warning !!': |
#|   shinylive does not work in self-contained HTML documents.
#|   Please set `embed-resources: false` in your metadata.
#| standalone: true
#| viewerHeight: 650

library(shiny)
library(bslib)
library(ggplot2)

# =============================================================================
# Simulated genome-wide association study (GWAS)
#
# Sliders set the number of SNPs, how many are truly associated (causal), the
# per-allele effect size, and the sample size. Each SNP's association test
# statistic is simulated directly from its non-centrality rather than by fitting
# a regression, which keeps it fast for tens of thousands of SNPs:
#
#   * null SNP:    z ~ N(0, 1)
#   * causal SNP:  z ~ N(mu, 1),   mu = beta * sqrt(N * 2*MAF*(1-MAF))
#
# so power grows with effect size, sample size and allele frequency exactly as
# in a real study. p = P(chi^2_1 > z^2). A multiple-testing correction
# (none / Bonferroni / Benjamini-Hochberg FDR) is applied and the corresponding
# significance threshold is drawn on the Manhattan plot. Causal SNPs are
# coloured so true positives, missed causal SNPs and false positives are all
# visible.
#
# To run:
#   install.packages(c("shiny", "ggplot2"))
#   shiny::runApp("gwas_sim_app.R")
# =============================================================================


M_MAX <- 50000L
# Approximate human autosome sizes (Mb), chromosomes 1..22, for laying out x.
CHR_SIZES <- c(249, 243, 198, 191, 181, 171, 159, 145, 138, 134, 135,
               133, 114, 107, 102, 90, 83, 80, 59, 64, 47, 51)

# ---- A fixed "genome": stable random pieces generated once -------------------
make_genome <- function(M_max = M_MAX, seed = 42) {
  set.seed(seed)
  list(
    z0  = rnorm(M_max),                       # null noise, per SNP
    maf = runif(M_max, 0.05, 0.50),           # minor allele frequency
    sgn = sample(c(-1, 1), M_max, TRUE)       # direction of effect
  )
}

# Deterministic genomic layout for the first M SNPs (no randomness, so stable).
layout_snps <- function(M) {
  total <- sum(CHR_SIZES)
  u     <- ((seq_len(M) - 0.5) / M)           # evenly spread across the genome
  gpos  <- u * total                          # cumulative position (Mb)
  chr   <- findInterval(gpos, cumsum(CHR_SIZES)) + 1L
  chr   <- pmin(chr, length(CHR_SIZES))
  list(gpos = gpos, chr = chr)
}

# ---- Run one simulation ----------------------------------------------------
simulate_gwas <- function(genome, M, m_causal, beta, N, alpha, method) {
  idx <- seq_len(M)
  z0  <- genome$z0[idx]; maf <- genome$maf[idx]; sgn <- genome$sgn[idx]
  lay <- layout_snps(M)

  causal <- logical(M)
  if (m_causal > 0) {
    ci <- unique(round(seq(1, M, length.out = m_causal)))
    causal[ci] <- TRUE
  }

  # Non-centrality shift for causal SNPs; observed z = noise + shift
  ncp <- beta * sqrt(N * 2 * maf * (1 - maf))
  z   <- z0
  z[causal] <- z0[causal] + sgn[causal] * ncp[causal]

  p    <- pchisq(z^2, df = 1, lower.tail = FALSE)
  padj <- p.adjust(p, method = method)
  sig  <- padj < alpha

  # Every method reduces to a single raw-p threshold on the Manhattan plot
  thr_p <- switch(method,
    none       = alpha,
    bonferroni = alpha / M,
    BH         = if (any(sig)) max(p[sig]) else NA_real_
  )

  df <- data.frame(
    gpos = lay$gpos, chr = lay$chr,
    p = p, logp = pmin(-log10(p), 40),   # cap for display
    causal = causal, sig = sig
  )

  attr(df, "summary") <- list(
    M = M, m_causal = sum(causal), n_sig = sum(sig),
    TP = sum(sig & causal), FP = sum(sig & !causal),
    FN = sum(!sig & causal),
    power = if (sum(causal) > 0) sum(sig & causal) / sum(causal) else NA_real_,
    fdr   = if (sum(sig) > 0) sum(sig & !causal) / sum(sig) else NA_real_,
    thr_p = thr_p, method = method, alpha = alpha
  )
  df
}

# ---- Manhattan plot --------------------------------------------------------
COLS <- c(null_odd = "#c3c7cc", null_even = "#9aa0a6",
          FP = "#d62728", FN = "#ff7f0e", TP = "#2ca02c")

manhattan_plot <- function(df) {
  s <- attr(df, "summary")

  cat <- ifelse(df$chr %% 2 == 1, "null_odd", "null_even")
  cat[df$causal & df$sig]   <- "TP"
  cat[df$causal & !df$sig]  <- "FN"
  cat[!df$causal & df$sig]  <- "FP"
  df$cat <- factor(cat, levels = names(COLS))

  bounds <- c(0, cumsum(CHR_SIZES))
  mids   <- (head(bounds, -1) + tail(bounds, -1)) / 2

  is_null <- df$cat %in% c("null_odd", "null_even")
  gw_line <- -log10(5e-8)                       # conventional GWAS threshold
  thr_line <- if (is.finite(s$thr_p)) -log10(s$thr_p) else NA

  p <- ggplot() +
    geom_point(data = df[is_null, ],
               aes(gpos, logp, colour = cat), size = 0.55, alpha = 0.75) +
    geom_point(data = df[df$cat == "FP", ],
               aes(gpos, logp, colour = cat), size = 1.7) +
    geom_point(data = df[df$cat == "FN", ],
               aes(gpos, logp, colour = cat), size = 1.9) +
    geom_point(data = df[df$cat == "TP", ],
               aes(gpos, logp, colour = cat), size = 2.1) +
    geom_hline(yintercept = gw_line, linetype = "dotted", colour = "grey55") +
    annotate("text", x = 0, y = gw_line, vjust = -0.5, hjust = 0,
             size = 3, colour = "grey45", label = "genome-wide 5e-8") +
    scale_colour_manual(
      values = COLS, drop = FALSE, name = NULL,
      breaks = c("TP", "FN", "FP"),
      labels = c("True positive (causal, detected)",
                 "False negative (causal, missed)",
                 "False positive (null, detected)")) +
    scale_x_continuous(breaks = mids, labels = seq_along(CHR_SIZES),
                       expand = expansion(mult = 0.01)) +
    labs(x = "Chromosome", y = expression(-log[10](italic(p)))) +
    guides(colour = guide_legend(override.aes = list(size = 3))) +
    theme_bw(base_size = 13) +
    theme(panel.grid.minor = element_blank(),
          panel.grid.major.x = element_blank(),
          legend.position = "bottom")

  if (is.finite(thr_line)) {
    lab <- paste0(switch(s$method, none = "uncorrected",
                         bonferroni = "Bonferroni", BH = "BH-FDR"),
                  " threshold")
    p <- p +
      geom_hline(yintercept = thr_line, linetype = "solid",
                 colour = "#1a1a1a", linewidth = 0.6) +
      annotate("text", x = max(df$gpos), y = thr_line, vjust = -0.5,
               hjust = 1, size = 3.2, colour = "#1a1a1a", label = lab)
  }
  p
}

# ---- UI --------------------------------------------------------------------
ui <- fluidPage(
  tags$head(tags$style(HTML("
    body { font-family: 'Segoe UI', Roboto, Helvetica, Arial, sans-serif; }
    .metric-card { border:1px solid #e3e3e3; border-radius:10px;
      padding:10px 14px; margin-bottom:10px; background:#fafafa; }
    .metric-label { font-size:12px; color:#666; text-transform:uppercase;
      letter-spacing:.03em; }
    .metric-value { font-size:22px; font-weight:600; color:#1a1a1a; }
    .metric-sub { font-size:12px; color:#555; }
  "))),

  titlePanel("Simulated GWAS: power, false positives, and multiple-testing correction"),

  sidebarLayout(
    sidebarPanel(
      width = 3,
      sliderInput("M", "Number of SNPs tested",
                  min = 5000, max = M_MAX, value = 20000, step = 5000),
      sliderInput("mc", "Number of truly associated (causal) SNPs",
                  min = 0, max = 300, value = 25, step = 1),
      sliderInput("beta", "Per-allele effect size (SD units)",
                  min = 0, max = 0.20, value = 0.10, step = 0.005),
      sliderInput("N", "Sample size",
                  min = 500, max = 50000, value = 8000, step = 500),
      tags$hr(),
      radioButtons("method", "Multiple-testing correction",
                   choices = c("None (raw p)" = "none",
                               "Bonferroni" = "bonferroni",
                               "Benjamini-Hochberg (FDR)" = "BH"),
                   selected = "bonferroni"),
      selectInput("alpha", "Significance level (alpha)",
                  choices = c("0.01" = 0.01, "0.05" = 0.05, "0.10" = 0.10),
                  selected = 0.05),
      helpText("Coloured points are causal SNPs (green = detected, orange = ",
               "missed). Red points are null SNPs that reached significance ",
               "(false positives). The solid line is the chosen threshold; ",
               "the dotted line is the conventional 5e-8.")
    ),

    mainPanel(
      width = 9,
      fluidRow(
        column(3, uiOutput("powerCard")),
        column(3, uiOutput("fdrCard")),
        column(3, uiOutput("countsCard")),
        column(3, uiOutput("thrCard"))
      ),
      plotOutput("manhattan", height = "460px")
    )
  )
)

# ---- Server ----------------------------------------------------------------
server <- function(input, output, session) {

  genome <- reactive(make_genome())          # generated once, cached

  sim <- reactive({
    simulate_gwas(genome(), input$M, input$mc, input$beta, input$N,
                  as.numeric(input$alpha), input$method)
  })

  card <- function(label, value, sub) {
    div(class = "metric-card",
        div(class = "metric-label", label),
        div(class = "metric-value", value),
        div(class = "metric-sub", sub))
  }
  pct <- function(x) if (is.na(x)) "n/a" else sprintf("%.0f%%", 100 * x)

  output$powerCard <- renderUI({
    s <- attr(sim(), "summary")
    card("Power (sensitivity)", pct(s$power),
         sprintf("%d of %d causal detected", s$TP, s$m_causal))
  })
  output$fdrCard <- renderUI({
    s <- attr(sim(), "summary")
    card("Observed false-discovery", pct(s$fdr),
         sprintf("%d of %d hits are false", s$FP, s$n_sig))
  })
  output$countsCard <- renderUI({
    s <- attr(sim(), "summary")
    card("Discoveries", format(s$n_sig, big.mark = ","),
         sprintf("TP %d | FP %d | FN %d", s$TP, s$FP, s$FN))
  })
  output$thrCard <- renderUI({
    s <- attr(sim(), "summary")
    val <- if (is.finite(s$thr_p)) formatC(s$thr_p, format = "e", digits = 1) else "none"
    card("Significance threshold (p)", val,
         sprintf("alpha = %s, %s SNPs", s$alpha, format(s$M, big.mark = ",")))
  })

  output$manhattan <- renderPlot(manhattan_plot(sim()))
}

shinyApp(ui, server)
5.11 Questions
- Set the number of SNPs to 20,000 and the number of truly associated SNPs to 100, with effect size of 0.06 and the sample size of 8000. Report the power of the test and the FDR for the unadjusted, Bonferroni, and FDR methods.
- Keep the same settings, except reduce the effect size to 0.04. Report the power of the test and the FDR for the unadjusted, Bonferroni, and FDR methods.
- Keep the same settings, except increase the effect size to 0.08. Report the power of the test and the FDR for the unadjusted, Bonferroni, and FDR methods.
- Across different scenarios, what difference do you see between the unadjusted and the Bonferroni corrected results?
- Across different scenarios, what difference do you see between the Bonferroni and the FDR-corrected results?